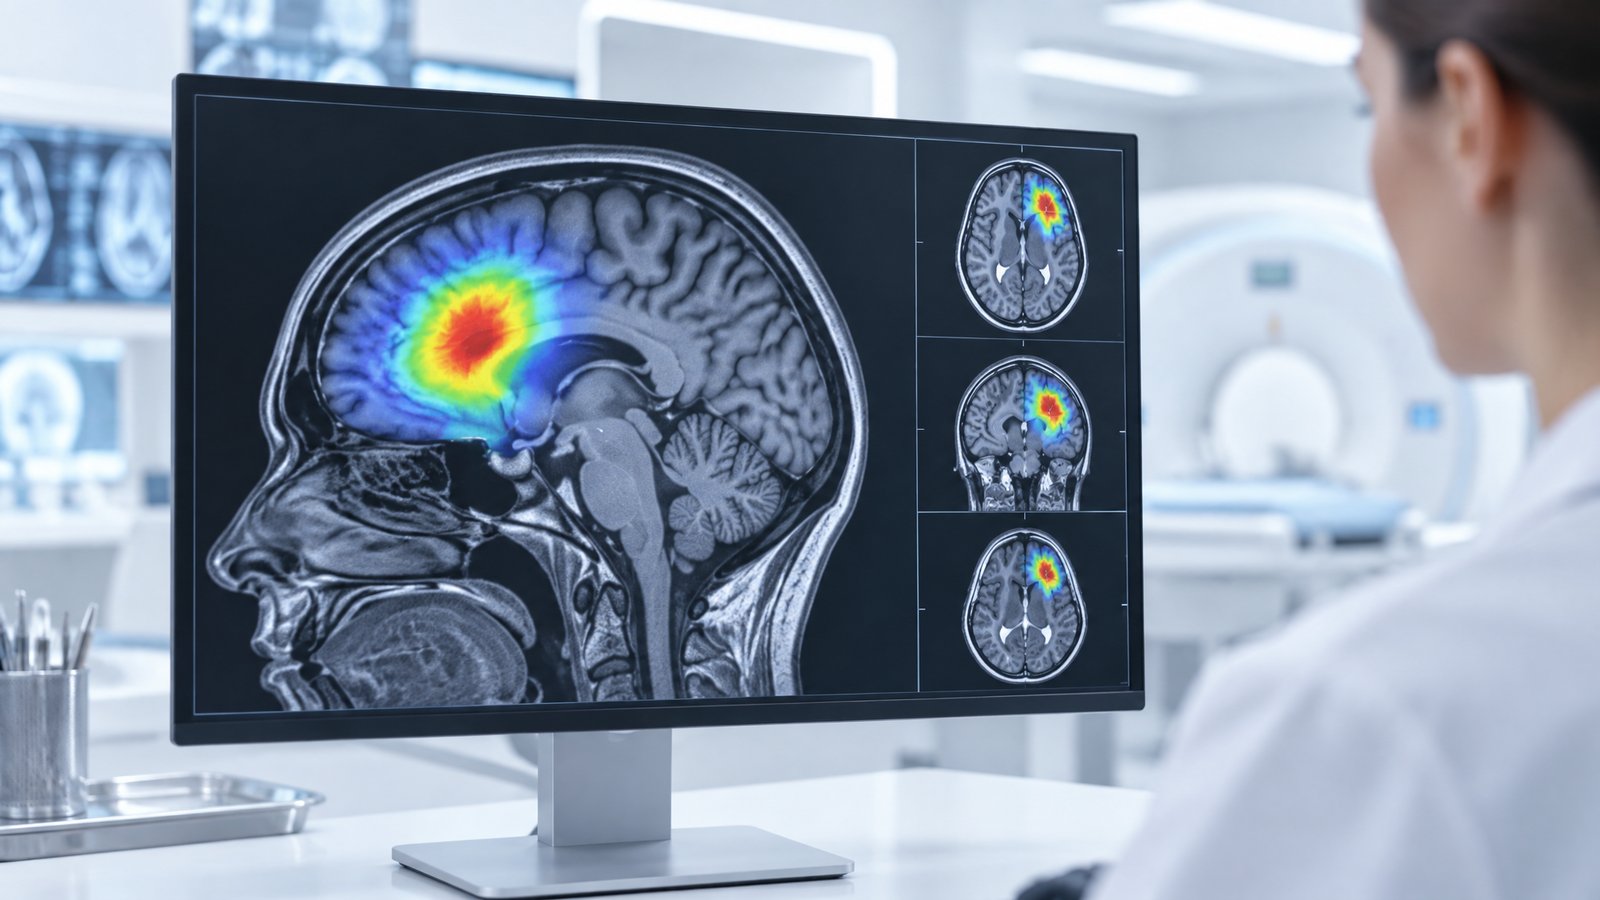
One of the most frequent questions we hear from radiologists is simple: "Why did the AI flag this?" It's the right question. A medical AI that can't explain itself is hard to trust — and shouldn't be trusted blindly. Today we're sharing how we've built explainability into every result Dinmar Labs produces.
Showing the evidence
Every finding our platform reports now comes with a visual heatmap overlaid on the original scan, showing which regions most influenced the model's decision. If the model flags a possible lesion, the clinician can immediately see whether the AI is focused on the lesion itself — or being distracted by an artifact or normal anatomy.
Calibrated confidence
A raw model score isn't the same as a probability. We've invested heavily in confidence calibration, so that when our system reports high confidence, that confidence is borne out by actual accuracy in validation data. Calibrated scores help radiologists decide how much weight to give each finding and help sites tune sensitivity to their clinical needs.
Measurements you can verify
- Automatic size, volume and density measurements for each finding
- Side-by-side comparison with prior scans, with change highlighted
- Slice-level navigation that jumps directly to the relevant images
Explainability as a safety feature
Explainability isn't just about trust; it's about safety. Visual explanations help clinicians catch the cases where AI is wrong, and help our engineers understand failure modes so we can fix them. It's a core part of our commitment to keeping clinicians firmly in the loop.
A Second Major University Joins as Clinical Trial Partner
Dinmar Labs Closes Its First Funding Round